Price terms as published
Each line is the vendor’s own wording, split from the price capture checked on 2026-09-22. Nothing here is rounded, converted or re-worded — the full sentences stay in the review below. Lines that carry only a price continue the plan named on the line above, in the vendor’s own order.
| # | Plan / term | Checked |
|---|---|---|
| 1 | Free (open source, Apache-2.0 | 2026-09-22 |
| 2 | LLM tokens BYOK) | 2026-09-22 |
One-liner: Open Code Review (ocr) reads Git diffs, drives a tool-using
LLM agent over them, and produces line-level review comments — hardened by two
years of internal Alibaba-scale use before going public in May 2026.
Verified facts (GitHub API + raw README, 2026-09-22 00:26–00:40 UTC+8)
| Attribute | Value | Source |
|---|---|---|
| GitHub stars | 39,049 (2,794 forks, 224 open issues+PRs) | alibaba/open-code-review via GitHub API, 2026-09-22 |
| License | Apache-2.0 | GitHub API license field |
| Language | Go | GitHub API |
| Created / published | 2026-05-18 | GitHub API |
| Last push | 2026-09-21 — daily activity | GitHub API |
| Origin claim | “Alibaba Group’s internal official AI code review assistant… tens of thousands of developers, millions of defects identified” | README intro (vendor claim, as translated) |
| Built-in rulesets | NPE, thread-safety, XSS, SQL injection, multi-language | README / repo description |
| Model wiring | OpenAI- & Anthropic-compatible endpoints (BYOK) | README |
| Delegation mode | ocr delegate preview / ocr delegate rule <files> — “let your AI coding agent perform the review itself… using its own LLM; no OCR API key required” |
README lines 164-190 |
| Efficiency claim | vs Claude Code same model: higher Precision/F1 at ~1/9 tokens; lower Recall by design | README benchmark blurb (vendor-run, treat accordingly) |
| Extras | ocr scan reviews whole files/dirs with no diff |
README |
The catches
- Benchmark numbers are the vendor’s own — the 1/9-token comparison was run by the team, not independently reproduced as of this check.
- The token economy is “delegate vs BYOK”: delegation reuses your existing agent subscription; BYOK bills you per token. Pick consciously.
- Lower recall is a stated design trade-off (“favoring precision over noise”) — it will miss things a general agent catches.
Who should use it
Teams wiring AI review into CI who want line-level comments with rule-pack coverage and provider-agnostic model choice — especially Alibaba-stack shops, and anyone whose coding agent already has tokens to spare (delegation mode).
All repo facts from GitHub API + raw README fetched 2026-09-22 (00:26–00:40 UTC+8); vendor claims labeled as such. No review run was executed for this page; no hands-on claims are made.
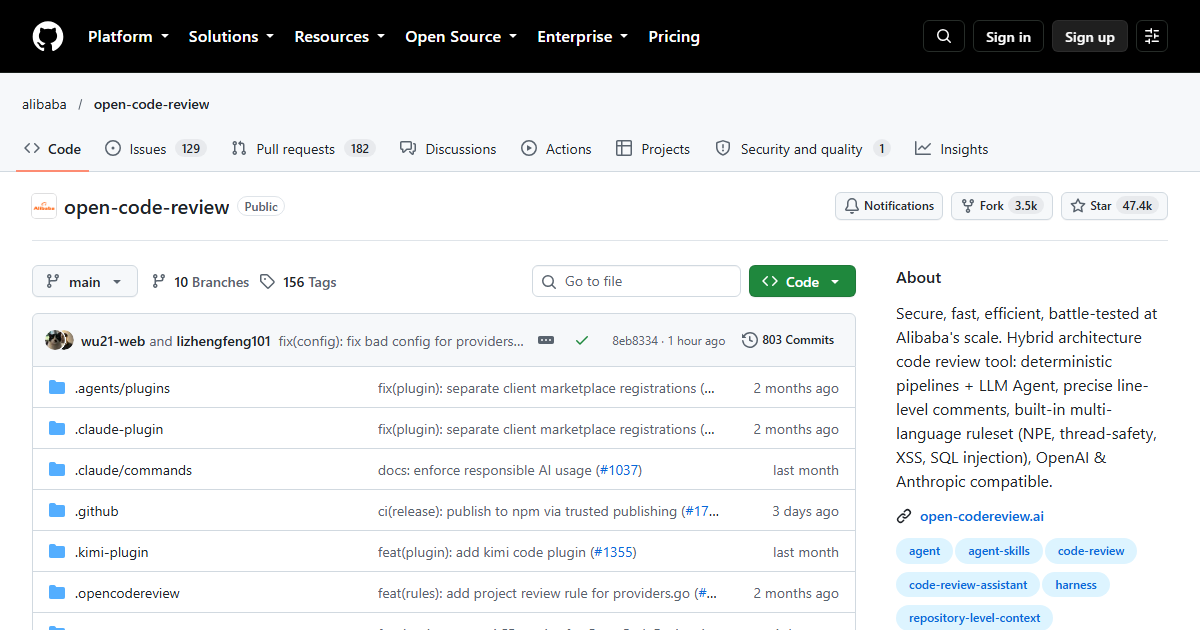
Repository facts (GitHub API + raw README, checked 2026-10-16)
| Attribute | Value |
|---|---|
| Stars / forks | 47,433 / 3,455 |
| Open issues | 313 |
| Licence | Apache-2.0 |
| Primary language | Go |
| Repository created | 2026-05-18 |
| Last push | 2026-10-16 |
| Archived | No |
| Homepage | open-codereview.ai |
| Topics | code-review, code-review-assistant, agent-skills, harness, repository-level-context |
Under five months from first commit to 47k stars, with a push on the day of this check. The
repository also publishes an npm package (@alibaba-group/open-code-review) and a Trendshift
badge, so installation is not confined to a source build.
The design claim, in the project’s own structure
The README is organised as an argument, and its section headings tell you the position before you read a paragraph:
- “What is Open Code Review?”
- “Benchmark”
- “Why Open Code Review?”
- “The Problem with General-Purpose Agents”
- “Core Design: Deterministic Engineering × Agent Hybrid”
The description line is the summary: “Secure, fast, efficient, battle-tested at Alibaba’s scale. Hybrid architecture code review tool: deterministic pipelines + LLM Agent, precise line-level …” — that is, the deterministic part finds the diff surface and runs known checks, and the agent part explains and prioritises what the pipeline found. For a reviewer, this is the interesting claim to test: a tool that never lets the model invent where the change is, only what it means.
How you actually run it (README’s usage section)
Prerequisites, then CLI install and a quick start, with four review scopes documented:
- Workspace mode — review all staged, unstaged and untracked changes.
- Branch range — review a feature branch’s changes since it diverged from
main(merge-base mode), i.e. only what the branch actually introduced. - Single commit — review one commit.
- Resume — pick up an interrupted range or commit review.
That fourth one matters more than it looks: review runs on real repositories are long enough to get interrupted, and a tool that can resume is one you will actually keep using.
What to verify before trusting the output
- “Battle-tested at Alibaba’s scale” is the vendor’s framing of its internal provenance. The benchmark section in the README is the project’s own comparison; reproduce it on a repository you know well before quoting any figure from it.
- BYOK is a workflow decision. If the agent leg needs your model key, code context leaves your machine for the provider — check what is sent (diff only, or repository context), whether snippets are redacted, and whether an offline/deterministic-only mode exists for sensitive code.
- Line-level precision is exactly where LLM reviewers get confidently wrong. Run it on a deliberately subtle change you have already reviewed by hand and compare the notes.
Source note: repository statistics come from the GitHub API; the section list, scope list, npm package name and description line come from the raw README read on 2026-10-16. No review was run for this entry, so no accuracy claim on this page is ours.